Should you move from Gemini 4 Argon to Hydrogen, or keep the model that already handles your work? A newer release only earns the switch when its answers need less checking, its workflow finishes reliably or its costs make more sense.
In this article, we compare their responses across four tasks: interpreting a diagram, auditing a CSV, repairing Python and writing a public notice. We then separate those results from published benchmarks and API pricing.
TLDR: Hydrogen met the diagram’s word limit and matched Argon on the recorded coding and writing checks. Its API rates are lower. Argon’s CSV record contains a screenshot–narrative conflict, so that round is unscored rather than counted as a loss.
What you get with each model
Gemini 4 Argon targets sustained coding, research and professional problem-solving. It became generally available on October 13. For an established workflow, the question is not whether Argon is older; it is whether another model delivers the required result more consistently or with less cost.
Gemini 4 Hydrogen arrived on November 12 with an execution-focused brief: everyday coding, multimodal analysis and tool use. It adds an Xhigh API thinking option alongside Low, Medium and High, but the paired outputs below come from the original High-thinking app tests.
| Feature / Metric | Gemini 4 Hydrogen | Gemini 4 Argon |
|---|---|---|
| Model ID | <gemini-4-hydrogen | gemini-4-argon |
| Primary Role | Fast execution, everyday coding, and agentic workflows | Balanced general-purpose and long-horizon reasoning |
| Context Window | 1,048,576 tokens (1M unified context) | 1,048,576 tokens (1M unified context) |
| Default Thinking Level | High | Medium |
| Supported Thinking Levels | Low, medium, high, xhigh | Low, medium, high |
| Standard Input Price | $1.50 per 1M tokens | $2.00 per 1M tokens (scheduled to rise to $4.00 on Dec 1, 2026) |
| Standard Output Price | $7.50 per 1M tokens | $10.00 per 1M tokens (scheduled to rise to $20.00 on Dec 1, 2026) |
| Free Tier Access | Available (subject to eligibility and quotas) | Not available |
| Intelligence Index Score | 51 (high) / 54 (xhigh) | 50 (high) |
These are text-output models. Image understanding does not mean native image generation, and a downloaded file also depends on the tools supplied by the app.
Task 1: Reading the uncertainty in a weather diagram
The first task used an actual image attachment. A red forecast line is easy to name; the more useful check is whether the model distinguishes two different uncertainty shapes and refuses numbers the schematic never supplies.
The filled cyan forecast uncertainty and the larger dashed cyan outline are different parts of the diagram.
Prompt
Explain the attached weather ensemble diagram in four numbered points, under 100 words total: (1) identify the red curve and thin blue curves; (2) describe how the ensemble spread changes from left to right; (3) distinguish the filled cyan area from the larger dashed cyan outline; (4) state whether the figure supports an exact temperature or probability of rain. Use only visible evidence. Do not browse or use other tools. Keep the response anonymous: no personal names, organisations, account details, contact information, personal references, or signature.
Gemini 4 Argon
Gemini 4 Hydrogen
Observation
Both correctly identified the deterministic forecast and the ensemble paths, explained the widening spread, and kept filled forecast uncertainty separate from dashed climatology. Each declined to invent an exact temperature or rain probability from the unscaled diagram. The reading itself offered little reason to switch models.
Argon returned 104 words, exceeding the requested under-100-word limit. Hydrogen used 95 and stayed within it. Both read the diagram correctly; Hydrogen’s advantage is meeting the complete response format without a trim, not a general vision-performance win.
Task 2: Auditing a telescope exposure file
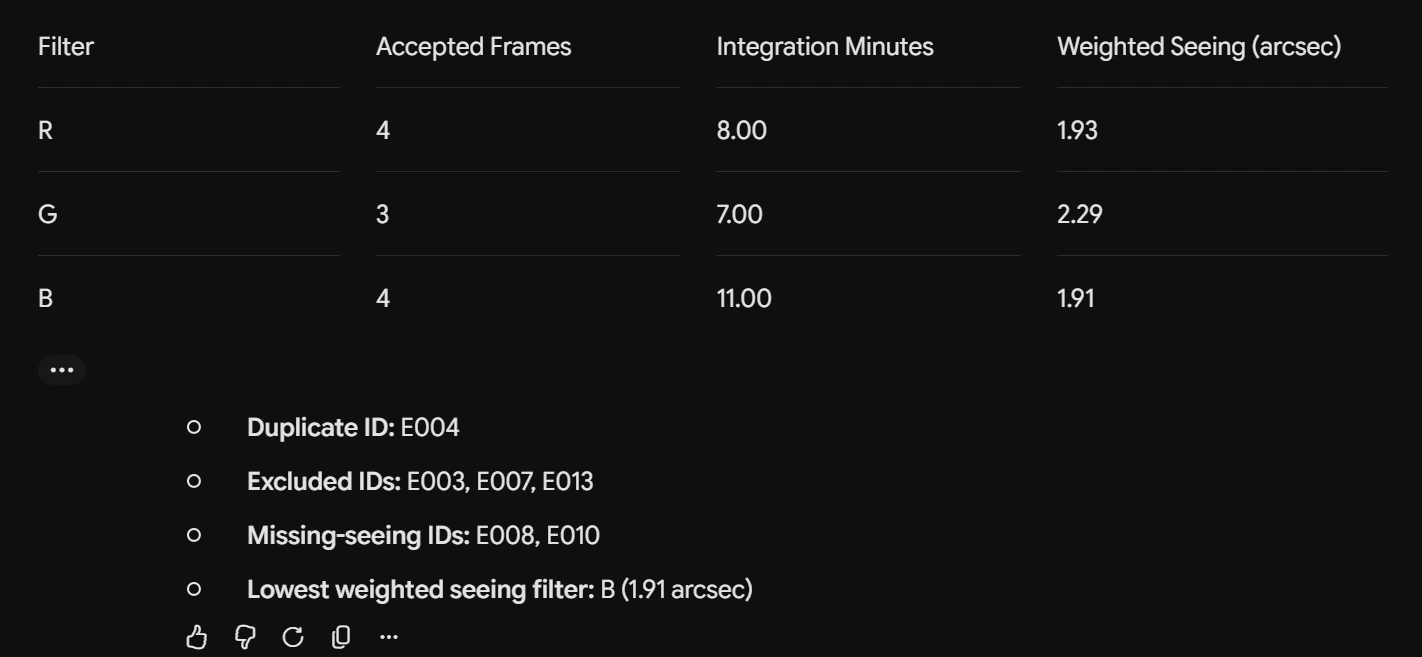
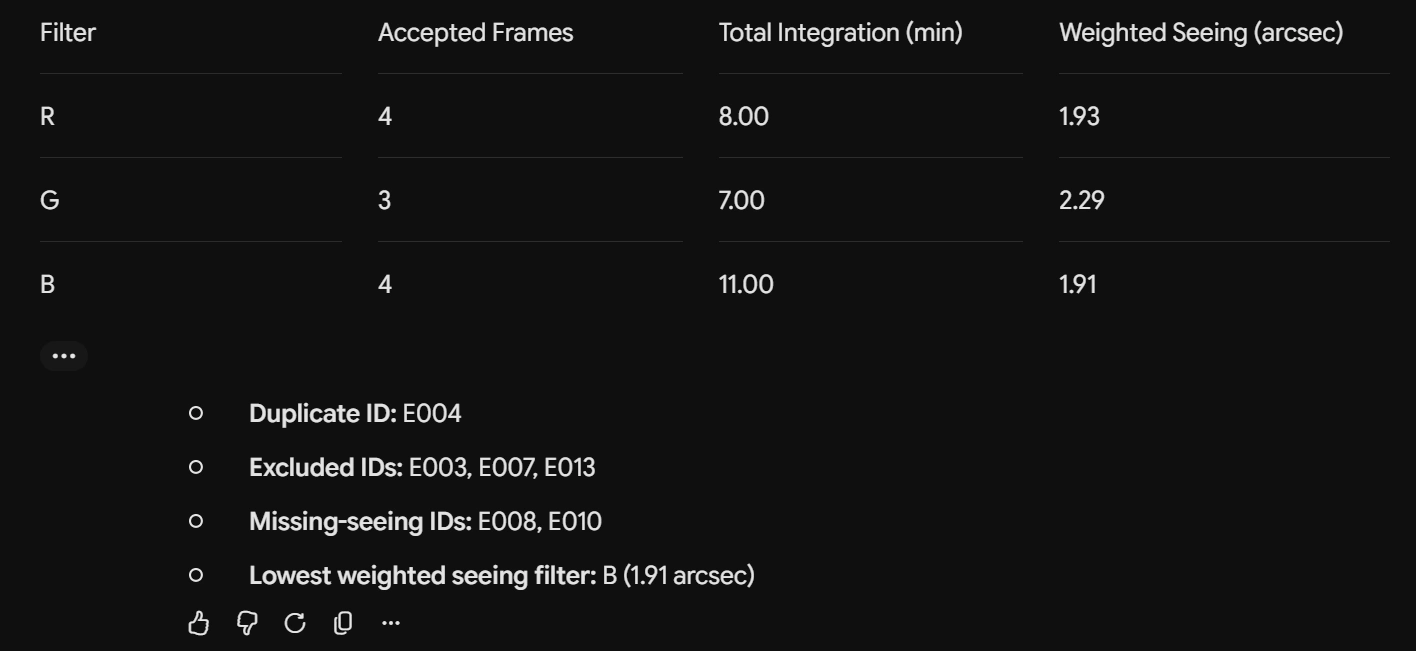
The CSV contained 15 rows, including one exact duplicate. After removing it and keeping accepted exposures, 11 frames remained. Two had no seeing value. Those frames still contributed exposure time, but could not contribute to the exposure-weighted seeing calculation. Dropping them from every total would quietly change the scientific record.
Input file
| exposure_id | filter | status | seconds | seeing_arcsec |
|---|---|---|---|---|
| E001 | R | accepted | 120 | 2.0 |
| E002 | R | accepted | 180 | 1.5 |
| E003 | R | rejected | 90 | 1.0 |
| E004 | G | accepted | 120 | 2.5 |
| E004 | G | accepted | 120 | 2.5 |
| E005 | G | accepted | 240 | 2.0 |
| E006 | B | accepted | 300 | 1.8 |
| E007 | B | pending | 180 | 1.3 |
| E008 | R | accepted | 60 | |
| E009 | G | accepted | 60 | 3.0 |
| E010 | B | accepted | 120 | |
| E011 | B | accepted | 180 | 2.2 |
| E012 | R | accepted | 120 | 2.5 |
| E013 | G | rejected | 600 | 0.8 |
| E014 | B | accepted | 60 | 1.6 |
Prompt
Audit the attached telescope exposure log. Remove the exact duplicate exposure once, then use only status=accepted. Return one compact table in filter order R, G, B with accepted-frame count, total integration minutes, and exposure-time-weighted seeing in arcseconds. Round the last two columns to two decimals. A missing seeing value must leave that frame in the count and integration total, but exclude its seconds from the seeing denominator. Below the table, name the duplicate ID, excluded IDs, missing-seeing IDs, and filter with the lowest weighted seeing. Use only the attached file; file-reading and calculation tools are allowed. Do not browse or create charts. Keep the whole answer under 150 words and anonymous: no personal names, organisations, account details, contact information, personal references or signature.
Gemini 4 Argon
Gemini 4 Hydrogen
Observation
Hydrogen returned all nine numeric cells and every requested record exception correctly through the allowed app tools. Its accepted-frame counts were 4, 3 and 4, integration totals were 8.00, 7.00 and 11.00 minutes, and weighted seeing was 1.93, 2.29 and 1.91 arcseconds for R, G and B.
The blue-filter observations had the lowest weighted seeing, just below red. Lower seeing generally means less atmospheric blurring; these records do not show that the filter caused the difference.
Task 3: Repairing an exact integer allocation function
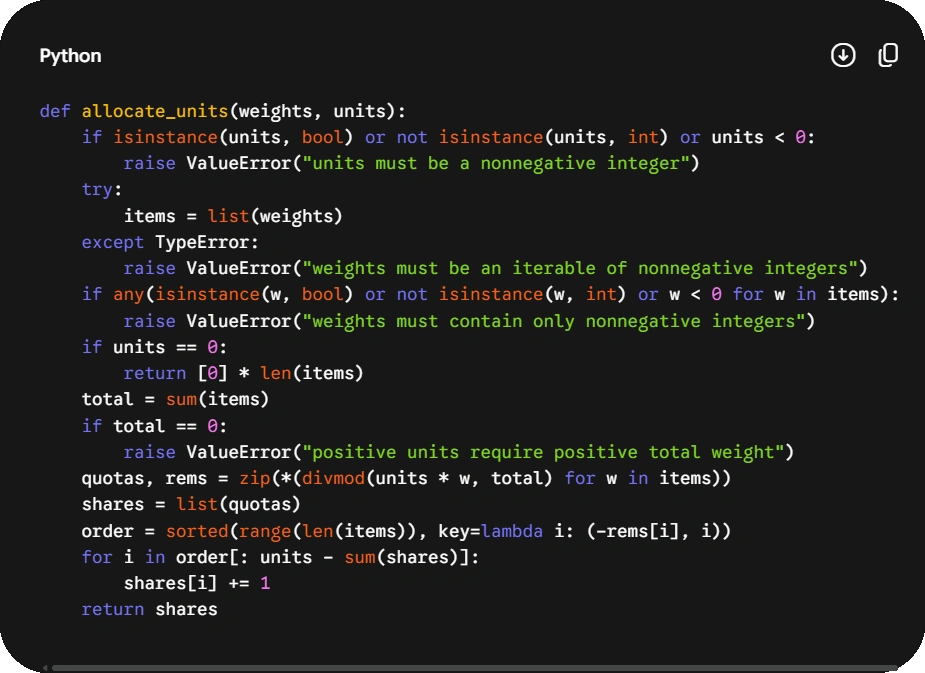
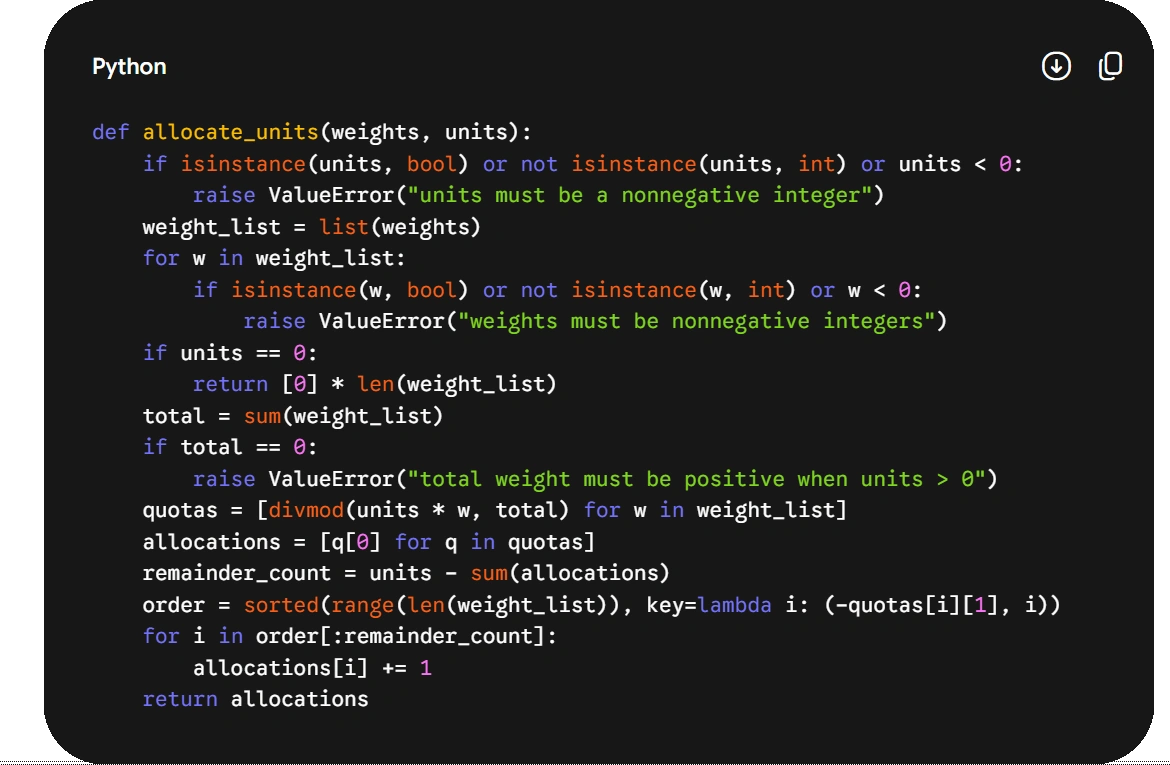
The Python attachment divided whole units in proportion to integer weights. Rounding each share independently can lose units or create extras; sorting the result can also detach an allocation from its original recipient. The requested repair had to conserve the total, retain input order and resolve equal remainders by original index.
Input function
def allocate_units(weights, units):
    total = sum(weights)
    shares = [round(units * weight / total) for weight in weights]
    missing = units - sum(shares)

    for index in range(missing):
        shares[index % len(shares)] += 1

    return sorted(shares, reverse=True)
Prompt
Repair
allocate_unitsin the attached Python file. Allocate a nonnegative integer number of units proportionally to a list of nonnegative integer weights using largest remainders: take each exact quota's floor, then give leftover units to the largest fractional remainders, breaking ties by original index. Return integer allocations in the original order and never mutate weights. Reject booleans, non-integer values and negative values with ValueError. If units is zero, return matching zeros, including[]for empty weights. If units is positive and weights is empty or totals zero, raise ValueError. Use exact integer arithmetic, not floating point. Return only the replacement function in one code block, at most 25 nonblank lines. Use only the standard library; do not browse or build an app. Keep every output anonymous: no personal names, organisations, account details, contact information, personal references or signature.
Gemini 4 Argon
Gemini 4 Hydrogen
Observation
Both functions passed the 19 fixed behavioral cases and 757 enumerated small cases, including validation, input preservation and the large-integer precision check. Each met the 25-line limit: Argon used 20 nonblank lines and Hydrogen 19. The checked contract was a tie; the small line-count difference does not establish a better repair.
The large-integer case is especially revealing: weights of 10^18 and 10^18 + 1 compete for one unit. Exact arithmetic must award it to the second weight. Converting the shares to floating point can erase the difference before the tie-breaking rule runs.
Task 4: Writing an update without promising a repair time
The last task used a text attachment about a water interruption. It had a confirmed next-update time but no confirmed restoration time. A fluent notice could still fail by turning noon into a promise, inventing safety advice or leaving readers unsure which buildings were affected.
Input notes
Water was turned off at 09:00 on Tuesday, 17 November 2026.

Only Buildings A and B are affected. Building C has normal water service.

A crew is repairing a valve. The repair is not yet complete.

There is no confirmed restoration time.

The next update will be issued at 12:00, even if there is no change.

Bottled water will be available in the courtyard from 10:00 to 12:00.

Toilets in Buildings A and B are closed during the interruption.

The accessible toilet in Building C remains open.

Visits scheduled in Buildings A and B before 12:00 are postponed.

Staff will contact affected visitors to rearrange those visits. No contact method is specified.

No information about drinking-water safety or the cause of the valve problem has been confirmed.
Prompt
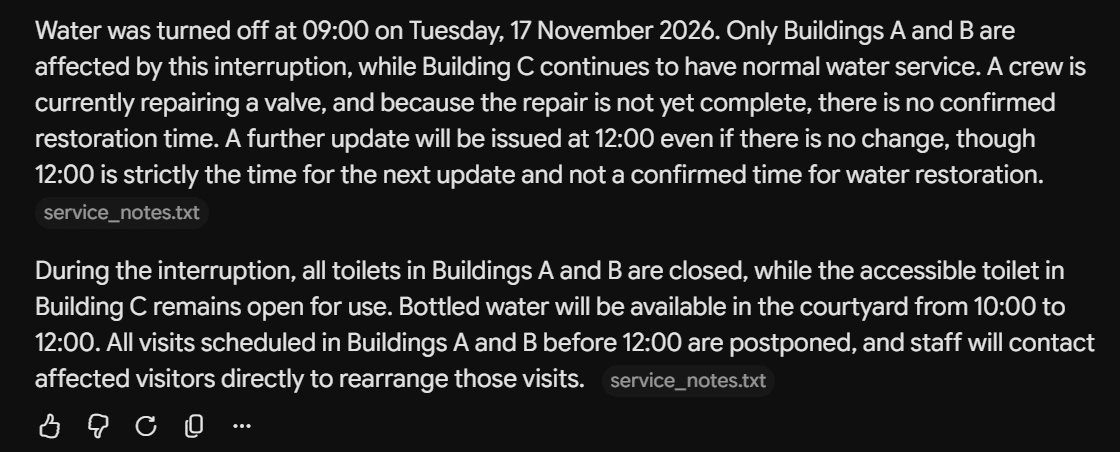
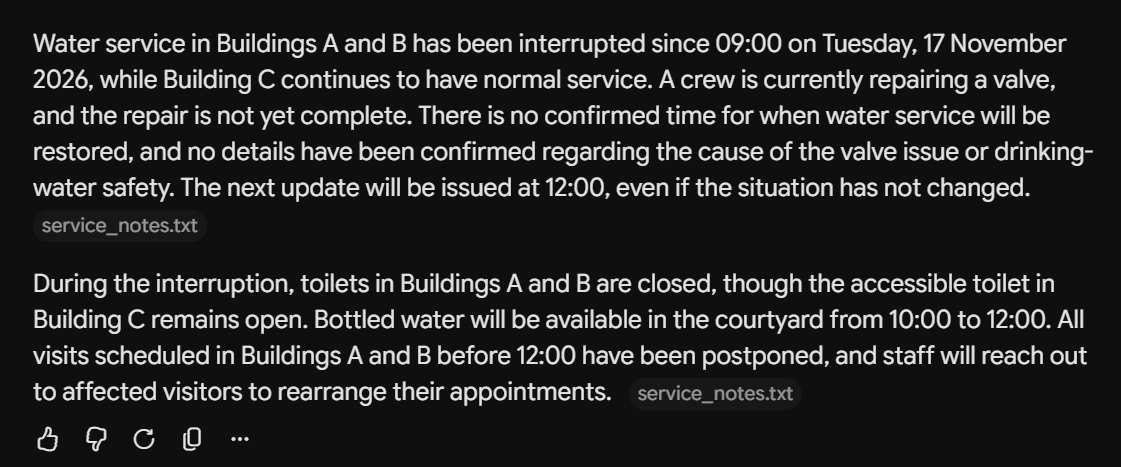
Turn the attached notes into a clear public update about the water interruption. Write 120–150 words in exactly two paragraphs, with no heading or bullets. Put the affected buildings and lack of a confirmed restoration time in the first paragraph. Preserve the dates, times, facilities and arrangements accurately. Make the distinction between the next update and restoration unmistakable. Use only the notes: do not invent a cause, safety advice, contact method, repair progress or promise. Return only the notice. Do not browse. Keep the output anonymous: no personal names, organisations, account details, contact information, personal references or signature.
Gemini 4 Argon
Gemini 4 Hydrogen
Observation
Both notices met the 120–150-word range in two paragraphs: Argon used 141 words and Hydrogen 139. They preserved the required facts and separated the noon update from an unconfirmed restoration time. Hydrogen also included the notes’ unconfirmed cause and safety information. Argon repeated the distinction about noon; I’d shorten that clause before posting while keeping the timing clear.
What the four tasks actually separate
| Task | Argon | Hydrogen |
|---|---|---|
| Weather diagram | Correct reading; 104 words, over the cap | Correct reading; 95 words, within the cap |
| CSV audit | Unscored: screenshot and narrative conflict | All nine numeric cells and exceptions correct |
| Python repair | Passed the recorded checks; 20 lines | Passed the recorded checks; 19 lines |
| Public notice | Facts preserved; 141 words | Facts preserved; 139 words |
Hydrogen earns the narrow instruction-following edge on the diagram, while coding and writing remain ties on the recorded requirements. The CSV record needs reconciliation, so it does not support an overall accuracy score. Do not turn an incomplete evidence trail into a model failure.
Published benchmarks
| Published benchmark | Argon · Oct results | Hydrogen · Nov report |
|---|---|---|
| SWE-sweep | 4.3% | 13.5% |
| Agents’ Last Exam v1.1 | 69.0% | 71.6% |
| OSWorld-2.1 (offline subset) | 74.7% | 77.6% |
| Vending-Bench 2 (bank balance, USD) | $13,718 | $14,549 |
| Chartography | 71.6% | 66.6% |
Matching names do not establish matching agent setups, thinking effort or evaluation dates. Read this as cross-report context, not a controlled head-to-head leaderboard. No overall win count is calculated.
Google’s Hydrogen launch announcement also makes an explicit Intelligence Index comparison: Hydrogen scores 51 at High and 54 at Xhigh, against Argon’s reported 50. Those are index points, not percentages or our four-task pass rates; Argon’s effort setting is not specified in that announcement’s comparison.
Argon’s reported Chartography score is higher in the earlier report, despite Hydrogen’s higher headline index. Terminal-Bench is kept separate: Argon’s 57.1% is from 4.0 (AA); Hydrogen’s 57.0% is from cheating-adjusted 4.1. Near-equal numbers on different versions do not establish a tie.
Access and API pricing
Argon’s launch lists paid API access and Google AI Pro or Ultra access in the Gemini app. Hydrogen is available through AI Studio and the Gemini API; free Gemini users receive it through automatic model selection where appropriate.
To reproduce the recorded app setup, open a fresh Gemini chat, choose the exact model where your plan allows it, select High thinking and wait for each attachment to finish uploading before sending the prompt. Keep these app settings separate from the API defaults listed earlier.
| Standard API rate (USD) | Argon | Hydrogen |
|---|---|---|
| Input / 1M tokens, through Nov 30, 2026 | $2.00 | $1.50 |
| Output / 1M tokens, through Nov 30, 2026 | $10.00 | $7.50 |
| Input / 1M tokens, from Dec 1, 2026 | $4.00 | $1.50 |
| Output / 1M tokens, from Dec 1, 2026 | $20.00 | $7.50 |
At standard uncached rates for 100k input and 10k output tokens, Hydrogen costs $0.225 compared to Argon's $0.30 (rising to $0.60 in December). Actual costs vary with thinking output, tools, and retries.
Which model should you choose?
I’d give Hydrogen the next bounded task first. It stayed within the diagram’s word cap, matched Argon’s checked code and writing results, and has lower published API rates. That is a practical starting point, not a claim that it dominates every kind of reasoning.
Our Gemini 4 Argon review covers a different set of practical tasks. Those results provide additional examples to inspect which didn’t fit in this article.
You also do not have to use one model for every step. Google describes Orchestrator switching between planning and execution models in Antigravity. You can also look at the Carbon vs Argon vs Hydrogen comparison to make the choice.
Frequently Asked Questions
Which model followed the diagram prompt better?
Hydrogen met the word limit at 95 words. Argon’s 104-word answer was accurate but exceeded the cap.
Did Argon fail the CSV arithmetic?
That is not established. The source narrative and retained screenshot conflict, so Argon’s CSV result remains unscored.
Which model won the coding task?
Neither. Both passed the recorded behavioral and enumerated checks and met the 25-line limit.
Do matching thinking levels make this controlled?
No. The tests used the same prompts and High setting, but app tools and compute budgets were not equalized.